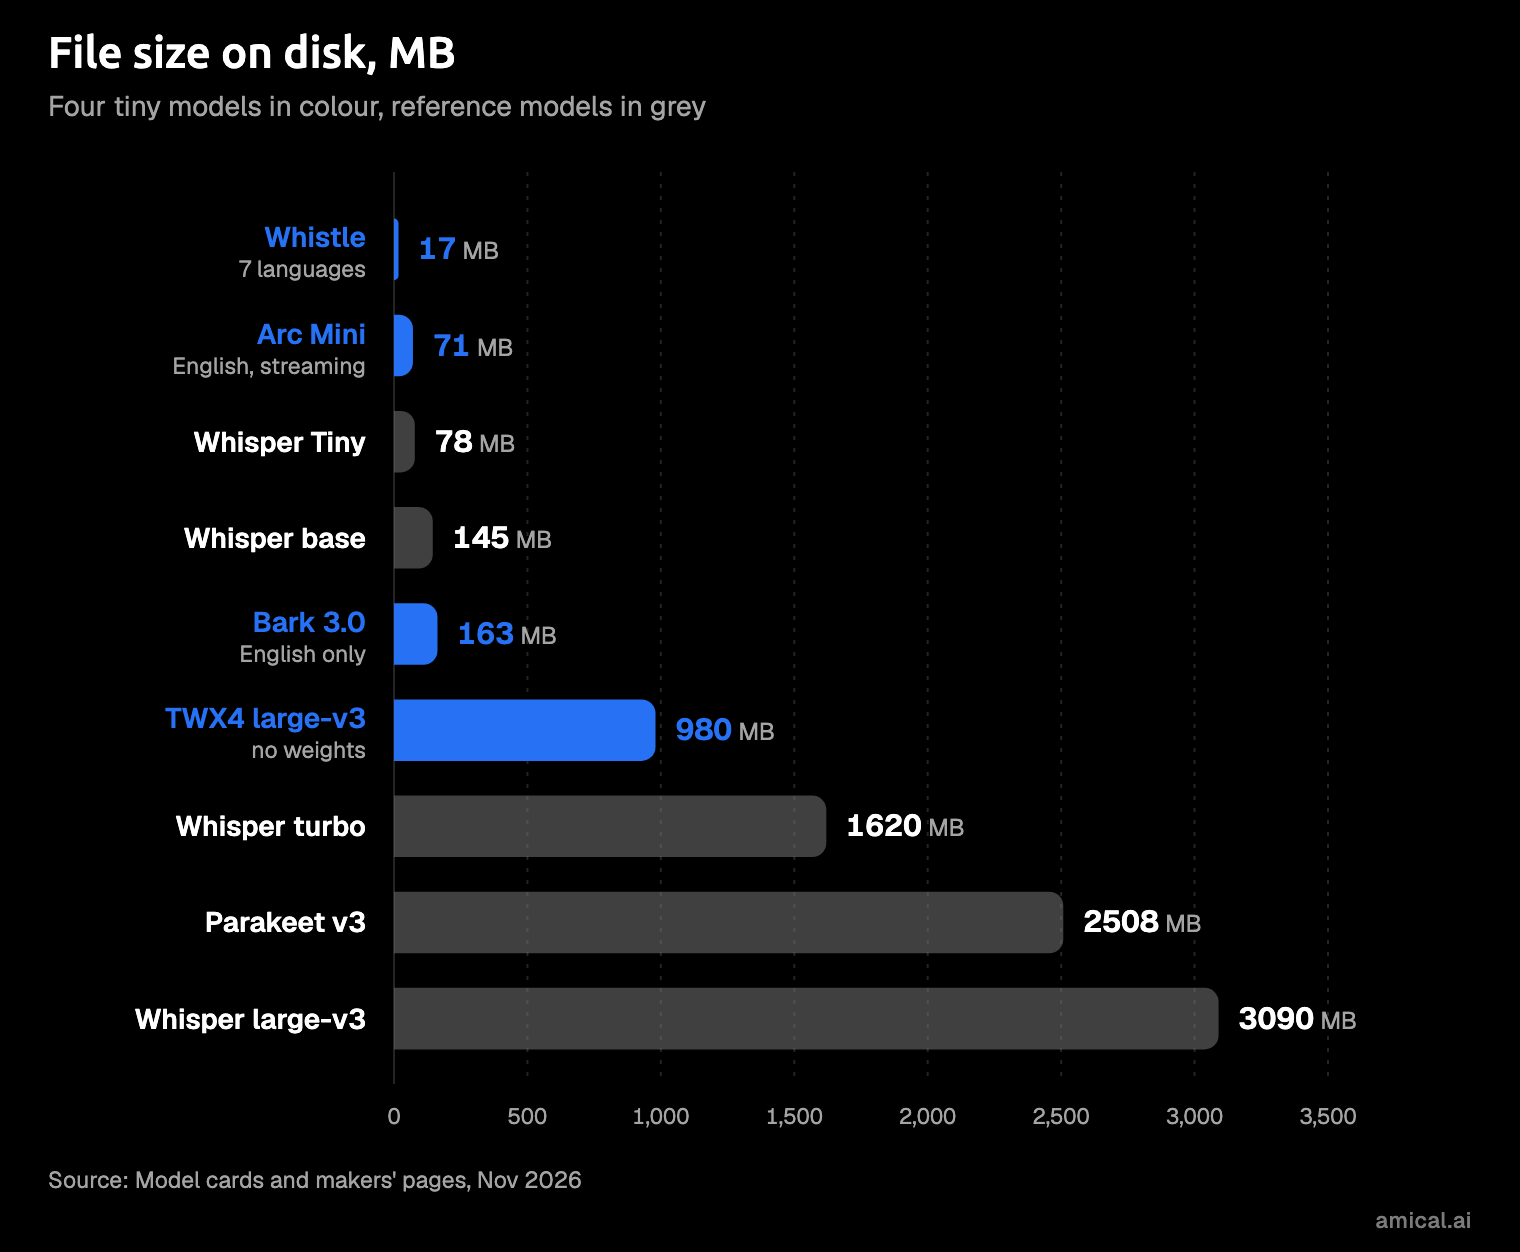
If you run speech-to-text on your own computer, your feed filled up with tiny models in October 2026: Whistle, Arc, Underdog Bark, and a Whisper that's "68% smaller". The headlines say a small speech recognition model now beats Whisper. The smallest, Whistle, is a single 16.9 MB file.
They're four different things. Whistle is a fresh release from Cactus Compute, Arc Mini is a modified Moonshine model that's honest about trailing Whisper, Bark is a compressed Parakeet, and TWX4 is a compressed Whisper whose page links no weights. None of them clearly beats the models you'd already run in a dictation app.
So when you read "beats Whisper", ask two things: which Whisper, and on what audio?
Amical publishes this blog, and Amical's local mode already runs Whisper and Parakeet, so you should know we have a stake in the answer. Amical Cloud is how we make money; local dictation is free. If you want the full-size models, see our guide to the best speech recognition models.
The four tiny models at a glance
The four models are built by different makers for different jobs, and each maker chose its own opponent, which matters more to you than any single number. Two well-known models sit at the bottom of the table so you have something to measure against: Whisper large-v3-turbo from OpenAI and Parakeet TDT 0.6B v3 from NVIDIA.
| Model (maker) | Size on disk | Languages | Streaming | Licence | Runs on | Maker compares it with |
|---|---|---|---|---|---|---|
| Whistle (Cactus Compute) | 16.9 MB | 7, auto-detect | No, clips up to 30 s | Apache-2.0 on the model card | CPU; 17 prebuilt targets incl. macOS, Linux, Android, iOS, watchOS, Windows on ARM, browser | Whisper base |
| Arc Mini (Whissle) | About 71 MB (4-bit) | English only | Yes, 100 ms chunks | CC BY-NC 4.0, non-commercial only | CPU | Whisper base.en, Moonshine |
| Underdog Bark 3.0 (Conway Research) | 163 MB | English only | Not stated | CC BY-NC 4.0 on the model card | Apple Silicon (MLX, Core ML); PyTorch elsewhere | Parakeet v3, Whisper large-v3 |
| TWX4 large-v3 (Tileward) | 0.98 GB | Tested on English and 7 FLEURS languages | Not stated | None published | vLLM on a GPU server | Whisper large-v3 |
| Whisper large-v3-turbo (OpenAI) | 1.62 GB per Tileward; about 1.5 GB in Amical | 99 | Not stated | MIT | Amical local mode on Mac and Windows | Reference |
| Parakeet TDT 0.6B v3 (NVIDIA) | 2,508 MB | 25 European | No, in Amical | CC BY 4.0 | Amical local mode on Mac (incl. Intel) and Windows | Reference |
"Tiny" here runs from 17 MB to nearly 1 GB, so the word tells you very little. If you put Whistle and TWX4 in one bucket, you're comparing a scooter to a bus because both have wheels.
The new models' accuracy scores in the four sections below are their makers' own, and the baseline rows beside them are published or leaderboard figures that nobody re-ran for the comparison. We found no independent replication of any of them, so you should read them as claims rather than results.
Whistle: a real 17 MB model, compared with Whisper base
Whistle is Cactus Compute's new speech model, released on October 2, 2026, as one 16.9 MB file that runs on the CPU with no dependencies. Cactus ships it prebuilt for 17 targets, from macOS and Linux through Android, iOS, watchOS, and the browser. It handles seven languages (English, German, French, Spanish, Italian, Dutch, and Polish) and detects which one you're speaking. You can feed it clips of up to 30 seconds, and it doesn't stream, so you'll need to cut longer recordings into chunks first. The Hugging Face card lists Apache-2.0, though Cactus's launch post names no licence.
Slow down when you reach the accuracy chart. In Cactus's own chart, as reported by eesel.ai, Whistle scores 4.31% WER on LibriSpeech test-clean against 4.9% for Whisper base, and 21.4% against 24.5% on a seven-language FLEURS average. Whisper base wins on meeting audio (AMI) and multilingual audiobooks (MLS), where Whistle scores 26.07% and 24.9%. The Whisper figures are the ones Whisper's authors published, not a fresh run.
Notice the opponent. Whisper base is a 145.3 MB model, so Whistle is beating a small Whisper, not the one you'd dictate with. One Hacker News user also reported Whistle repeating "Thank you." over long, messy audio, which is exactly what a clean test set won't show you.
It's still impressive for its size. If you're building voice commands for a phone, a watch, or a web page, Whistle is the one to watch.
Arc Mini: honest about losing
Arc Mini is Whissle's small English streaming model, a modified version of Moonshine Streaming tiny, the MIT-licensed model from Useful Sensors. It's the only small streaming "Arc" we found, so that's the one covered here. The download is about 71 MB, it's English only, and it streams text in 100 ms chunks while you talk. The licence is CC BY-NC 4.0 for non-commercial use only, and if you want commercial use, you need a separate written licence from Whissle.
If you're building a product, that last line settles it.
Its maker's table is unusually candid. In Whissle's own numbers, Arc Mini scores 8.5 and 22.9 on LibriSpeech clean and other, against 4.2 and 9.8 for Whisper base.en. On meeting audio (AMI) it scores 35.3 against 29.5. It trails Whisper base.en on all six of its maker's test sets, and the model card tells you so plainly.
The pitch is something else: one small streaming model that also tags names, numbers, and events as it goes. That's useful if you're running a research project, and it's a different job from dictation. If live streaming is what drew you here, our post on Nemotron streaming ASR covers a larger model built for it.
This is the most trustworthy table of the four, precisely because it shows the loss. A vendor that shows you its own losing numbers has earned a little extra belief.
Underdog Bark 3.0: a compressed Parakeet
Underdog Bark 3.0 isn't a new model. Conway Research post-trained and compressed NVIDIA's Parakeet TDT 0.6B v3 into a 163 MB file, released on October 21, 2026. It's English only (inside the Underdog app, other languages fall back to Whisper large-v3-turbo), and it runs on Apple Silicon through MLX or Core ML, or through PyTorch on other machines. It doesn't support custom words yet, which matters if your sentences are full of product names. And if you'd ship it in a paid app, ask Conway first: the model card lists CC BY-NC 4.0.
The headline comes from Underdog's own table. Across seven English test sets, Bark averages 4.94% WER, the same as Parakeet v3 and ahead of Whisper large-v3 at 6.04%. At three decimals it's 4.937 against 4.941, a tie in any sense you'd notice. The Parakeet and Whisper rows are Open ASR Leaderboard figures as of October 9, 2026, while Bark's own row was scored with the leaderboard's code but isn't listed there. That row is plain Bark 3.0, which writes your filler words down; the Underdog app uses a separate Clean model for dictation.
Set by set, what you get is mixed. Bark beats both rivals on meetings (AMI), GigaSpeech, and VoxPopuli, and trails Parakeet on the other four. Against Whisper large-v3 it wins four of the seven sets and loses LibriSpeech clean, LibriSpeech other, and SPGISpeech.
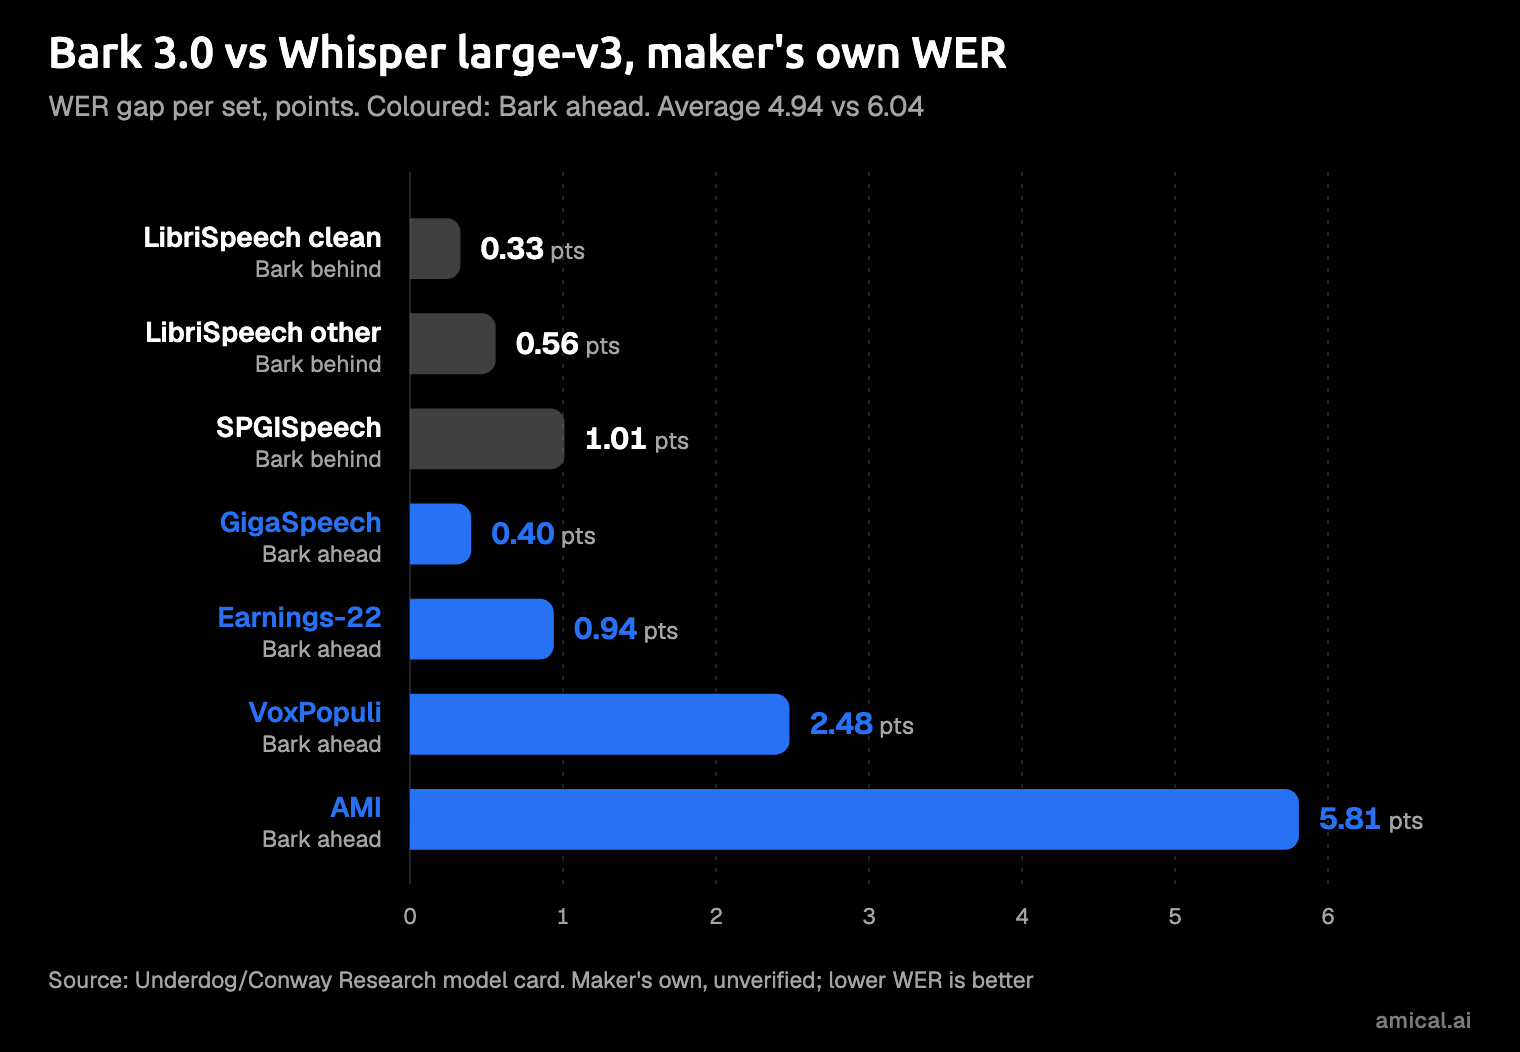
Bark's gap to Whisper large-v3 on each set, in WER points, by our arithmetic from Underdog's own table. Unverified, no independent replication found. Parakeet isn't shown.
Against the one other model its size on the card, Bark wins on average: Phonon-2, at 164 MB, averages 5.21% to Bark's 4.94%, though Phonon-2 wins four of the seven sets. Underdog's own bigger Bark 3.0 Plus, at 180 MB, beats both with 4.76%. Even the underdog has a bigger sibling.
So the real headline is about Parakeet. Underdog's size column lists Parakeet at 2,508 MB and Bark at 163 MB, so by our arithmetic Bark matches Parakeet's average at about a fifteenth of the size. That's good news for Parakeet, the model doing the heavy lifting. If you want the original, our Parakeet TDT v3 guide covers it.
Tileward TWX4: a 68% smaller file, not a smaller model in memory
TWX4 is Tileward's compressed build of Whisper large-v3, described in a post dated October 16, 2026. The weights file shrinks from 3.09 GB to 0.98 GB, which is where the "68% smaller" comes from. Once it's loaded on the GPU, though, the post says the weights take the same space as before. Tileward tested it on a vLLM server with one 20 GB card, where it handled 152 live calls against 140 for large-v3.
On accuracy, Tileward reports error rates within about 0.3 points of large-v3 on most sets, with two languages moving by more than a point, one in each direction. The page links no weights and lists no licence or parameter count, so for now there's nothing on it for you to try.
This is a server-cost story, not an on-device one. Think of it as a lighter zip file that unpacks to the same-size program on your server. OpenAI already ships an official smaller large-v3 in turbo, which cuts the decoder from 32 layers to 4. If you're weighing that trade, our Whisper large-v3-turbo vs large-v3 comparison covers it.
How to read a maker's WER claim
Each maker picks its own exam, and so far nobody else has sat it. WER, or word error rate, is the share of words a model gets wrong against a human transcript, so lower is better.
That doesn't make the numbers false. It means you should ask five questions before you believe a headline:
- Which baseline did they pick? Whistle chose Whisper base, Arc Mini chose Whisper base.en and Moonshine, and Bark chose Parakeet and Whisper large-v3. A small model looks great next to another small model.
- Which test sets? In Cactus's comparison, Whisper's meeting score uses the headset subset of AMI (AMI-IHM), a different subset from the one Whistle was scored on. Two numbers can share a name and still measure different audio.
- English only? Arc Mini and Bark are English only. Whistle's multilingual numbers are far higher than its English ones: 21.4% on FLEURS and 24.9% on MLS.
- Clean or messy audio? LibriSpeech is audiobooks read aloud, and its "other" set is the harder half. In each maker's own figures, Whistle goes from 4.31% on clean to 10.49% on other, and Arc Mini from 8.5 to 22.9. Your audio is probably closer to "other".
- How was the text normalised? The Open ASR Leaderboard strips punctuation and capital letters and removes filler words before scoring. Underdog's separate Bark "Clean" model also drops filler words itself, so check which variant a score belongs to.
That last point matters most if you dictate. WER ignores punctuation, capital letters, and formatting, which are the things you notice first when text lands in an email. Your colleague's misspelled name counts as one wrong word, the same as a dropped "the".
A low score on a test set read by professional narrators says little about your mumble in a Zoom room with the fan on.
When model size matters (and when it doesn't)
If you dictate on a recent laptop, file size is the least of your worries. Size decides on phones, watches, browsers, older laptops, and small offline devices. On a recent Mac or Windows PC it rarely does: Whisper large-v3-turbo, at about 1.5 GB in Amical, fits fine, and accuracy and your languages matter more. Our Parakeet vs Whisper comparison covers how the two full-size options trade off.
Each tiny model has a place, just not the same one:
- Whistle: voice commands and short clips on any of the maker's 17 prebuilt targets, from watchOS to the browser.
- Arc Mini: streaming English for research and other non-commercial projects.
- Underdog Bark 3.0: non-commercial English apps on Apple Silicon that want Parakeet's average accuracy in a smaller file.
- TWX4: GPU servers handling many calls at once, once Tileward publishes the weights.
The old Intel MacBook you keep in service is where size and speed start to bite. If that's yours, check a model's OS and chip requirements before its file size.
Pick for the audio you have first, then for size.
A small model that keeps getting your colleagues' names wrong costs you more time than the disk space it saves.
What to run for dictation today
A dictation app needs more than a model. You need a shortcut that starts recording, a way to type into whatever app you're in, formatting that turns speech into a proper message, and custom words for the names you say every day. None of the four tiny models is a dictation product; each one hands you raw text.
Amical is the worked example, and our pick if you dictate on a Mac or Windows PC. In local mode it runs Parakeet TDT 0.6B v3, the model behind Bark's headline score, and Whisper from Tiny (about 78 MB) up to Large v3 (about 3.1 GB), Large v3 Turbo included. You pick the model under Settings > AI Models > Speech > Default Speech Model. Whisper covers 99 languages and Parakeet covers 25 European ones, far more than Whistle, Arc Mini, or Bark.
Then it writes what you meant. AI formatting rewrites your words for the app you're in, using a local model through Ollama (a tool for running language models on your computer) or a cloud provider you choose. In local mode Amical needs no account, works offline once a model is downloaded, and no audio leaves your computer; text leaves only if formatting uses a cloud provider. The desktop app is open source under MIT, so you can check that on GitHub. See Local AI models for setup.
Where Amical falls short, and what you can do about it:
- No Whistle, Arc Mini, or Bark in Amical. Bark only ties the Parakeet that Amical already runs, and Whistle and Arc Mini are only measured against small Whispers.
- The smallest model is about 78 MB, not 17 MB. On a desktop that gap doesn't decide anything, and Whisper Tiny and Base are there for older machines.
- Local Whisper needs macOS 15 or later and is slower on Intel Macs. Parakeet runs on macOS 14 and Intel Macs, and Amical Cloud has no macOS requirement.
- Local Parakeet doesn't stream. You speak, then the text arrives, which suits an email or a Slack reply just fine.
- Phones don't run local models in Amical. The iPhone and Android apps use Amical Cloud and need sign-in.
The 163 MB headline is Parakeet squeezed down, and you'll find the full Parakeet already in Amical's model list. If you speak a language Parakeet doesn't cover, pick Whisper instead.
You don't need to wait for a 17 MB model to stop typing.
To try it, download Amical, set the speech model to Parakeet, and dictate the reply you've been putting off since this morning. The free plan includes unlimited local dictation and 2,000 cloud words a week; Pricing has the rest.